Published on 19 Nov 2026
min read
Views
Across most of the plants we work with, connectivity was solved years ago.
PLCs talk to SCADA, SCADA feeds a historian, and somewhere a pipeline copies tags into a data lake. Then a reliability engineer asks a fair question: which critical pumps are likely to fail before the next planned shutdown, and are the spares on site?
The answer still takes weeks of spreadsheet work – a gap that is the real OT/IT challenge of the AI era.
Streaming and publish/subscribe patterns have existed for decades, and moving data from a PLC, SCADA system, historian, or MQTT broker into an enterprise platform is no longer the challenge. What organizations increasingly need is the ability to turn high-frequency industrial signals into governed, reusable data products – with enough context and trust behind them so that analytics, machine learning, and operational decisions can depend on them.
On Databricks, that comes down to five architecture decisions.
1. Decide what earns a stream
Not every PLC tag needs a real-time pipeline. A vibration or bearing-temperature anomaly that needs attention within seconds may justify Structured Streaming, which on Databricks now includes a real-time mode for operational workloads. An hourly production counter does not. It is cheaper and simpler to land it as files and pick it up with Auto Loader or a scheduled job.
A useful test: if no person or system will act on a signal within minutes, it probably does not need to stream. At the other extreme, anything that must trip a machine in milliseconds belongs in the control layer, not the cloud. Latency, cost, reliability and operational value need to be weighed signal by signal.
2. Let the historian keep its job
Historians remain critical for plant operations, high-resolution time-series retention and control-room use cases.
Operators trust them, and ripping one out rarely justifies the disruption. Databricks does not need to replace the historian. The stronger pattern is to use the Lakehouse as the enterprise layer above it, the place for cross-domain analytics, AI, optimization and long-term industrial intelligence that no single plant’s historian was designed to deliver.
3. Build data products, not telemetry dumps
Landing OPC UA or MQTT payloads in Delta Lake tables is where the work starts. A tag called TT_4021_PV means little to a data scientist until it is tied to an asset hierarchy, maintenance history, production context, quality events and records from ERP, MES, CMMS and EAM systems.
During the announcement of our partnership with Databricks, it was evident that the bottleneck “has never been data; it’s been context.”
Here is what that looks like in practice. A vibration signal from a rotating asset streams into Delta Lake and is joined with the asset’s maintenance history to build a machine-health feature table. A model managed with MLflow scores it, and a rising risk score triggers a maintenance notification in SAP PM or whichever system the plant runs. Each step leaves behind something reusable, which is the difference between a data product and a pile of telemetry.
4. Govern from day one
“Let’s get the data in first and govern it later,” is one of the most expensive sentences in an industrial data program. By the time governance arrives, three teams have built three versions of the same tag mapping, and nobody can say which one feeds the model.
OT data needs lineage, ownership, quality rules, plant-level access controls, consistent semantics and auditability from the start. This is where Unity Catalog matters, because it applies one model of permissions, lineage and auditing to OT data, IT data and the models built on both.
5. Close the loop into operations
An equipment-health dashboard is not the finish line. Value appears when predictions change what happens on the floor: a work order created, a production plan adjusted, a quality risk flagged before the batch ships. That requires the industrial data platform to connect with ERP, MES, CMMS, quality systems and digital twin environments, so insight lands where planners and technicians already work. It’s the same reason our Asset Health Framework is built to act on what it diagnoses.
There is no single correct pattern
Depending on the plant landscape, both of these can be valid:
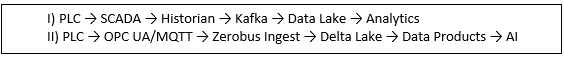
The first suits brownfield sites with mature historians and a Kafka backbone that already serves several consumers, while the second removes hops.
With Zerobus Ingest, lightweight forwarding agents at the edge push events straight into governed Delta tables, with no message bus acting as a staging area. Databricks is clear that it does not replace a bus when several operational systems consume the same events, so the choice depends on who else needs the data, not on which diagram looks more modern.
Where this is heading
The destination is a unified, governed data plane where operational systems, enterprise systems, analytics, and AI all work from the same trusted industrial data. Getting there takes as much plant engineering as data engineering, which is why our FactoryNext framework takes a vendor-neutral approach and builds on the IT and OT investments a plant already has.
The machine will always matter. But in the AI era, one of the most valuable assets on the shop floor is the governed data product built from that machine’s signals.