Executive Summary
A global engineering and construction organization runs its entire project delivery on ~1,000 engineering applications, used by a 15,000+ strong workforce spread across 80+ countries. When those applications stall, billable engineering hours stall with them.
LTTS took end-to-end ownership of the application lifecycle through a 5-year managed services engagement - a 24×7 offshore delivery centre governed by the ITIL (Information Technology Infrastructure Library) framework, layered with cloud modernization - cutting Priority-1 and Priority-2 incidents (critical and high-severity) by 70%, lifting application performance by up to 64%, and resolving 85% of tickets within two days.
Read the Full Case Study. Anytime, Anywhere
Download Case StudyThe Challenge
At this scale, application downtime is not an IT nuisance - it stalls billable engineering hours across live capital projects, in every geography at once. A fragmented, geography-by-geography support model could not hold the SLA (Service Level Agreement) bar, and gave the business no trend visibility into why the same issues kept returning. Adding more regional vendors would have deepened the fragmentation, not fixed it. What the client needed was a single, accountable partner to own the full IT/OT application landscape end-to-end - support, stability, performance, cloud migration, and continuous improvement - on a multi-year basis, with one service standard and one number to call.
Engineering Complexity
Individually, none of these four problems is unusual. Holding all four at once - on an application landscape that can never go offline - is what made this hard.
Scale and diversity of the landscape
~1,000 applications - Bentley, Autodesk, SmartPlant, ProjectWise, and a long tail of desktop, enterprise, and custom apps - each with its own release cadence and vendor dependency, all held to one service standard.
Round-the-clock global coverage
A 15,000+ user base spread across every major time zone meant “business hours” never closed - support had to be continuous and shift-based, without quality dropping between handovers.
High-volume ticket flow
300+ incidents and 400+ service requests a month, all within SLA - without recurring issues quietly re-entering the queue.
Continuous change on a live environment
Patching, upgrades, migrations, and enhancements delivered while the environment stayed live - every change window was somebody’s working hour.

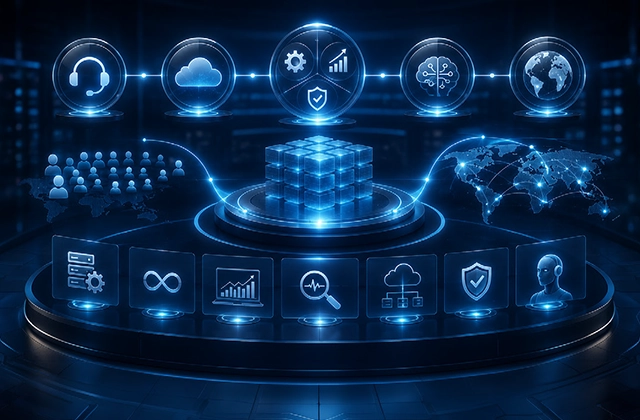
Offshore Delivery Excellence Centre
Single, consolidated owner of the ~1,000-application landscape - replacing fragmented, geography-by-geography support.

24×7 shift-based support on ITIL
Follow-the-sun coverage across all time zones with structured handovers - service quality held constant between shifts.

Shift-left: knowledge articles + trend identification
Recurring patterns mined into reusable knowledge and package fixes - cutting ticket volume at source, not just ticket time.

Proactive monitoring and alerts
Degradation flagged before users noticed - pre-empting critical and high-severity outages.

Re-architecting + configuration corrections
Architecture-rooted issues fixed and tuned geography by geography, rather than patched at the symptom.

Cloud migration + Azure / Windows Virtual Desktop rollout
Application landscape modernized on cloud, with performance tuned to each user location.
Business Outcomes
70%
Fewer critical and high-severity incidents
Priority-1 and Priority-2 volumes fell sharply across the engagement -driven by proactive monitoring and architecture-level fixes, not faster firefighting. Fewer outages reaching live capital projects, and materially less escalation overhead on both sides.
64%
Performance improvement across the application landscape
ProjectWise gained 38% through caching provisions, while Azure and Windows Virtual Desktop rollouts delivered 12%–64% improvements depending on user location - speed returned directly to the engineer’s desktop.
85%
Tickets resolved within two days
ProjectWise gained 38% through caching provisions, while Azure and Windows Virtual Desktop rollouts delivered 12%–64% improvements depending on user location - speed returned directly to the engineer’s desktop.
8%
YoY incident and 5% YoY service-request reduction
Delivered through shift-left, trend identification, and package corrections - shrinking the ticket base itself, so the cost of running the landscape falls even as the landscape grows.overhead on both sides.
Explore More Success Stories
From Bottlenecks to Breakthroughs: A Tier 1 Supplier’s Journey in Material Testing Excellence
In an industry where efficiency, cost management, and compliance are critical, one leading Tier 1 supplier headquartered in Japan redefines what's possible.
Know More